

A note on timing: this happened in September 2026, on Inspect AI 0.3.259 through 0.3.269.
This is a companion to our series of posts, where Ryan Hansz and I walk through the eval behind our SNAP results. Partway through that work, a whole family of models stopped working, and the fix ended up being in Inspect itself.
Inspect is free, open source software from the UK government’s AI Security Institute for testing AI models: you give it a set of questions with known answers, it asks each model, and it scores how often the model gets them right.
Every request crashed
When I first ran the full set of frontier models through Amazon Bedrock, OpenAI’s GPT-5.6 models (Sol, Terra and Luna) crashed on every single request.
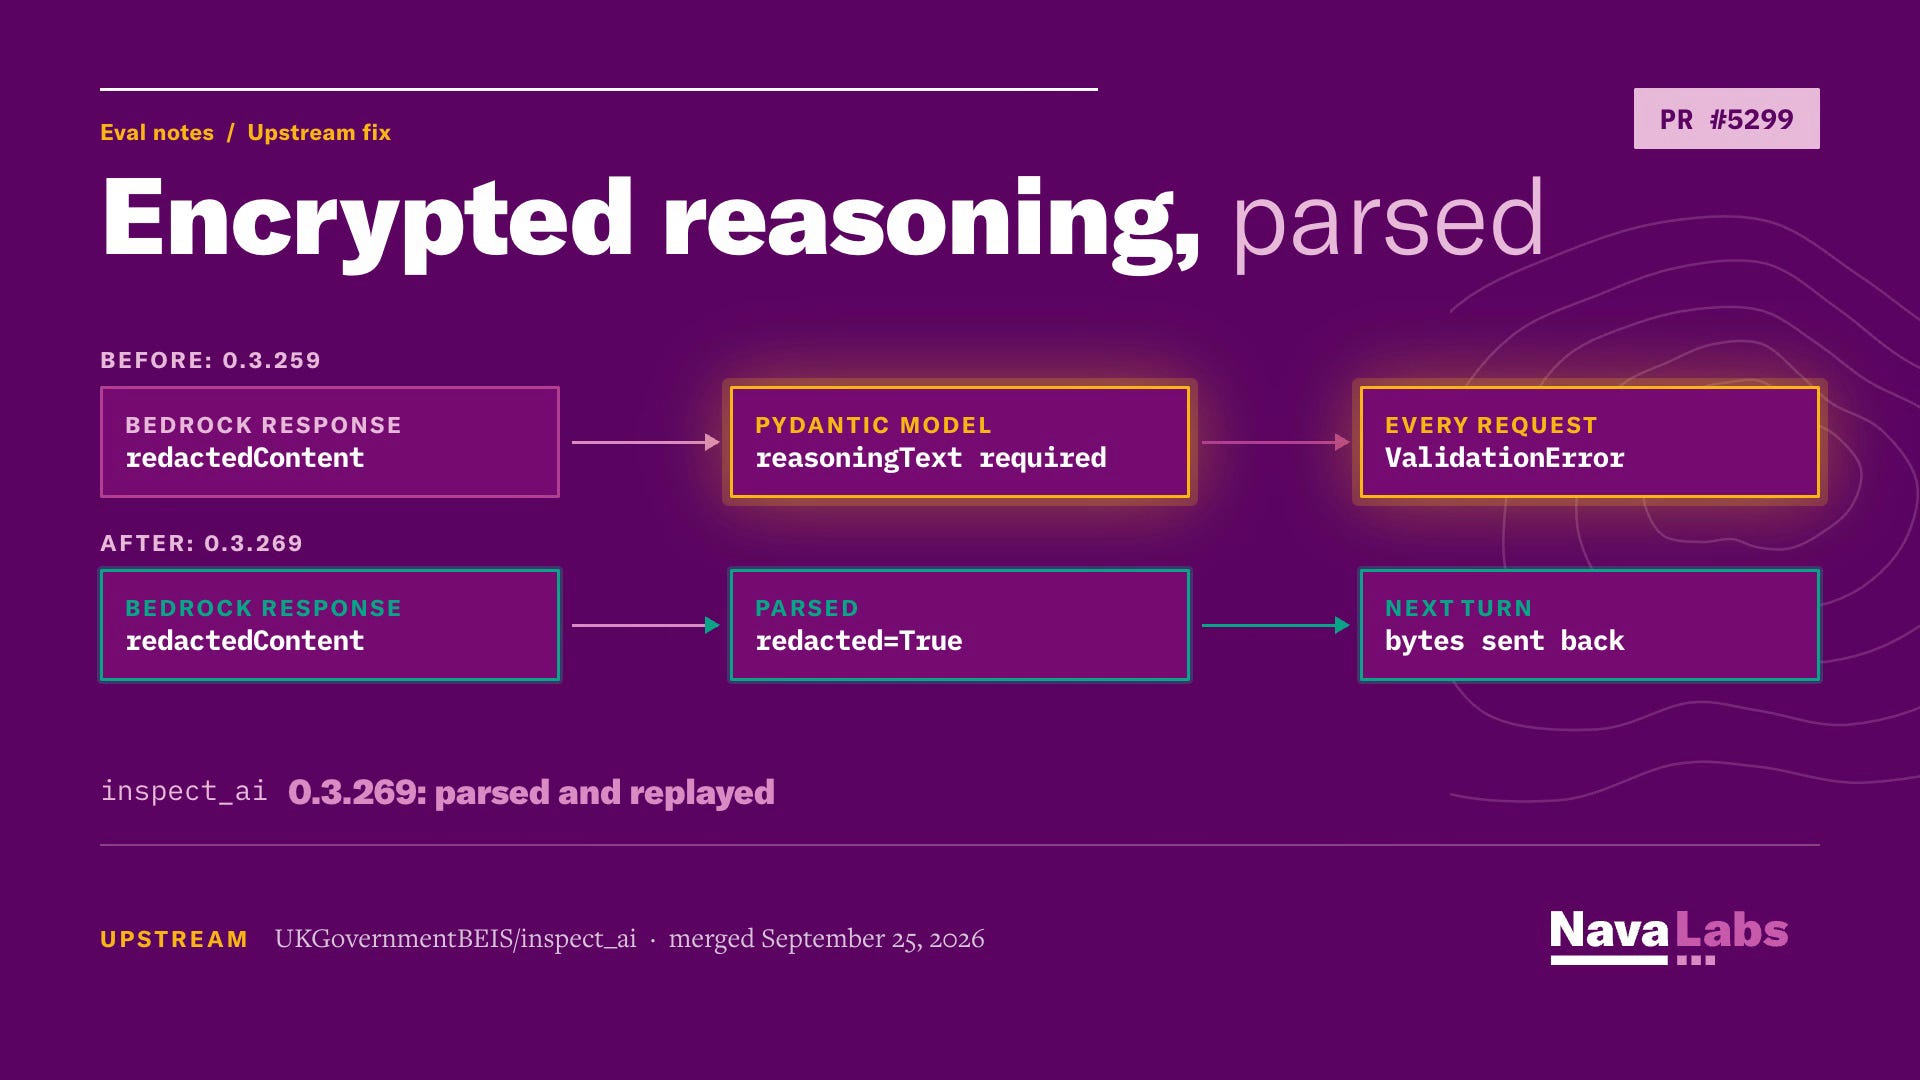
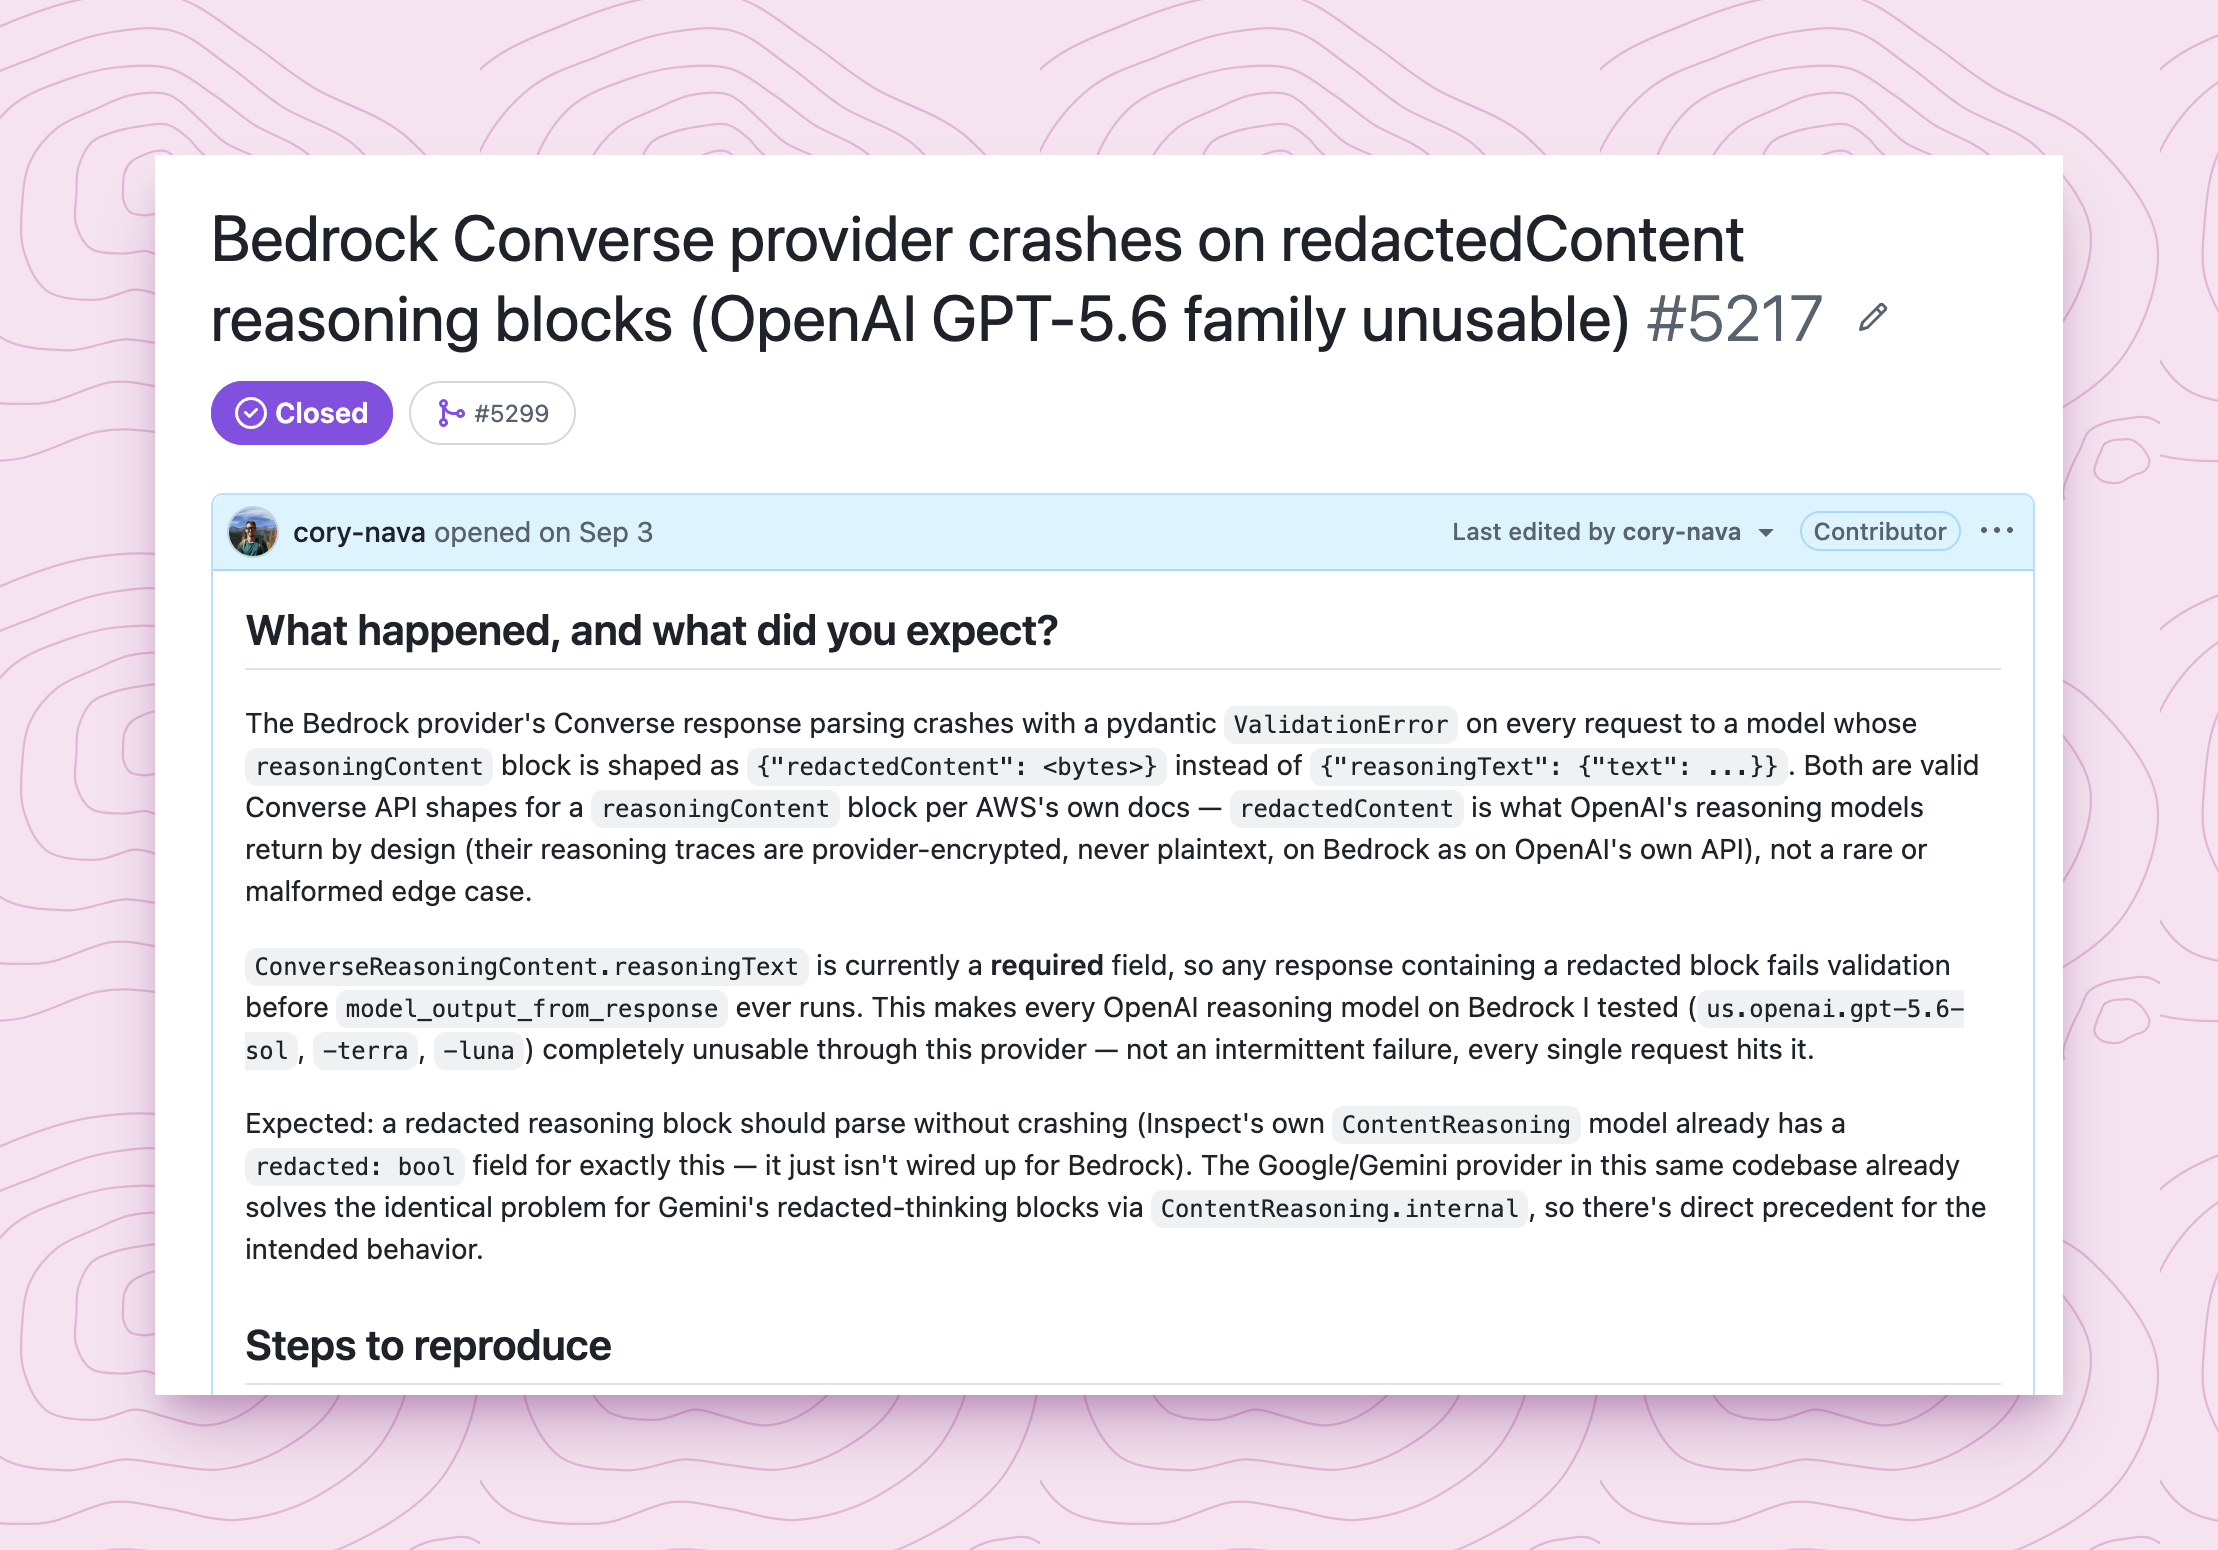
These models return their reasoning as an encrypted blob called redactedContent, never as readable text. That’s on purpose, and it’s a valid response shape in AWS’s API. But Inspect’s Bedrock provider only expected the readable shape, and its pydantic model marked the readable field as required. So every response failed validation before Inspect could even parse it:
ValidationError: 2 validation errors for ConverseResponse
output.message.content.0.reasoningContent.reasoningText
  Field required [type=missing, input_value={'redactedContent': b'rsn...'}, input_type=dict]
A raw aws bedrock-runtime converse call showed the API was fine. The bug was in Inspect. Reading the provider source (inspect_ai/model/_providers/bedrock.py) took about 10 minutes and saved me an afternoon of guessing.
Issue first, then the pull request
Inspect has an issue-first rule for outside contributors. You open a GitHub issue, a maintainer marks it accepted, and only then can you open a pull request. So I patched my local install to keep the eval moving, and then filed issue #5217 on September 3 with reproduction steps and a proposed fix.
One change became four
The fix ended up bigger than I planned. I’d scoped one change, and the merged pull request had four:
Parse the encrypted block instead of crashing.
Send the encrypted bytes back to the model on the next turn. Parsing alone fixed turn one, but it broke every multi-turn and tool-using eval at turn two. That’s most of what we run.
Do the same in the streaming path, so streamed and regular calls behave the same.
Swap in a placeholder for the bytes when writing the raw response to the log. The field is binary, and non-text bytes break the log’s text encoding.
It took three rounds of review with the maintainers. They caught things I had missed, including a crash I had found and then talked myself out of because my test data wasn’t realistic. Pull request #5299 merged on September 25 and shipped in Inspect 0.3.269. If you run OpenAI reasoning models through Bedrock in Inspect, they work now.
The review also turned up three related issues I filed afterward: #5300, #5301 and #5302.
Measuring AI on benefits questions only counts if the measuring tool is open and works for everyone, so we fixed the bug upstream instead of keeping a private patch.
What I’d take from it
When a provider crashes, make the sample, raw API call yourself. It tells you in one command whether the bug is upstream or in your code.
Read the provider’s source before you blame your config.
Test the second turn too. A fix that parses a response can still break the conversation that follows.
Patch locally to keep moving, but file the issue the same day while the repro is fresh.
It’s a small fix, and I’m still pretty happy that a SNAP eval led to a patch in the AI Security Institute’s own framework.
Amen on getting good measurements — and broadly applicable to so many other disciplines in addition to engineering. Also appreciate being able to follow the back-and-forth on GitHub... making that process visible helps to promote transparency and accountability :)